Representing text: ASCII and Unicode
플레이하며 배우기
이 문제들을 풀어 에너지를 얻은 뒤 낚시하고 탐험하세요. 계정이 필요 없어요.
교육자를 위해: Representing text: ASCII and Unicode(KS3 Computing, Computer Systems)을(를) 위한 바로 쓸 수 있는 수업 슬라이드, 복습 노트, 다이어그램 — 수업에 사용하거나, 학습자들이 실시간 게임으로 즐기는 인터랙티브 클래스 활동으로 진행하세요.
수업 노트
What is Character Encoding?
- Character encoding is a convention that uses a numeric value to represent each character in a writing script.
- It covers natural language symbols, plus control characters and whitespace.
- The numeric values are called code points; together they form a code space or code page.
- Encoded text can be stored, transmitted, and transformed by computers.
Early Character Encodings
- Early codes (e.g., Morse code, Baudot code) could only represent a limited set of characters, often just upper-case letters, numerals, and basic punctuation.
- Morse code (1840s) used four symbols (short signal, long signal, short space, long space) to create variable-length codes.
- Baudot code (1870) was a five-bit encoding, later standardized as ITA2 in 1930.
- Punch cards (late 19th century) encoded data by hole positions; later, alphabetic data used multiple punches per column.
- IBM's BCD (binary-coded decimal) encodings were six-bit and used in early computers like the IBM 702.
ASCII: The American Standard Code for Information Interchange
- ASCII is a widely used character encoding that maps each character to a 7-bit binary code (0–127).
- It includes upper and lower case letters, digits, punctuation, and control characters.
- ASCII can represent only 128 characters, which is enough for English but not for other languages.
- Because it uses 7 bits, ASCII text takes 1 byte per character (with the 8th bit often unused or used for parity).
Limitations of ASCII
- ASCII cannot represent characters from non-English languages (e.g., accented letters, Cyrillic, Arabic, Chinese).
- It also cannot represent emoji or many special symbols.
- To overcome this, various extended ASCII encodings (like ISO/IEC 8859) were created, but they were incompatible with each other.
- This led to the need for a universal encoding system.
Unicode: A Universal Character Set
- Unicode is a comprehensive encoding system that aims to represent every character from all writing systems, plus emoji and symbols.
- Each character has a unique code point (e.g., U+0041 for 'A').
- Unicode is extensible, meaning new characters can be added.
- It has replaced most earlier encodings because it solves the compatibility problem.
Text becomes computer-readable by mapping each character to a code point and then to binary.
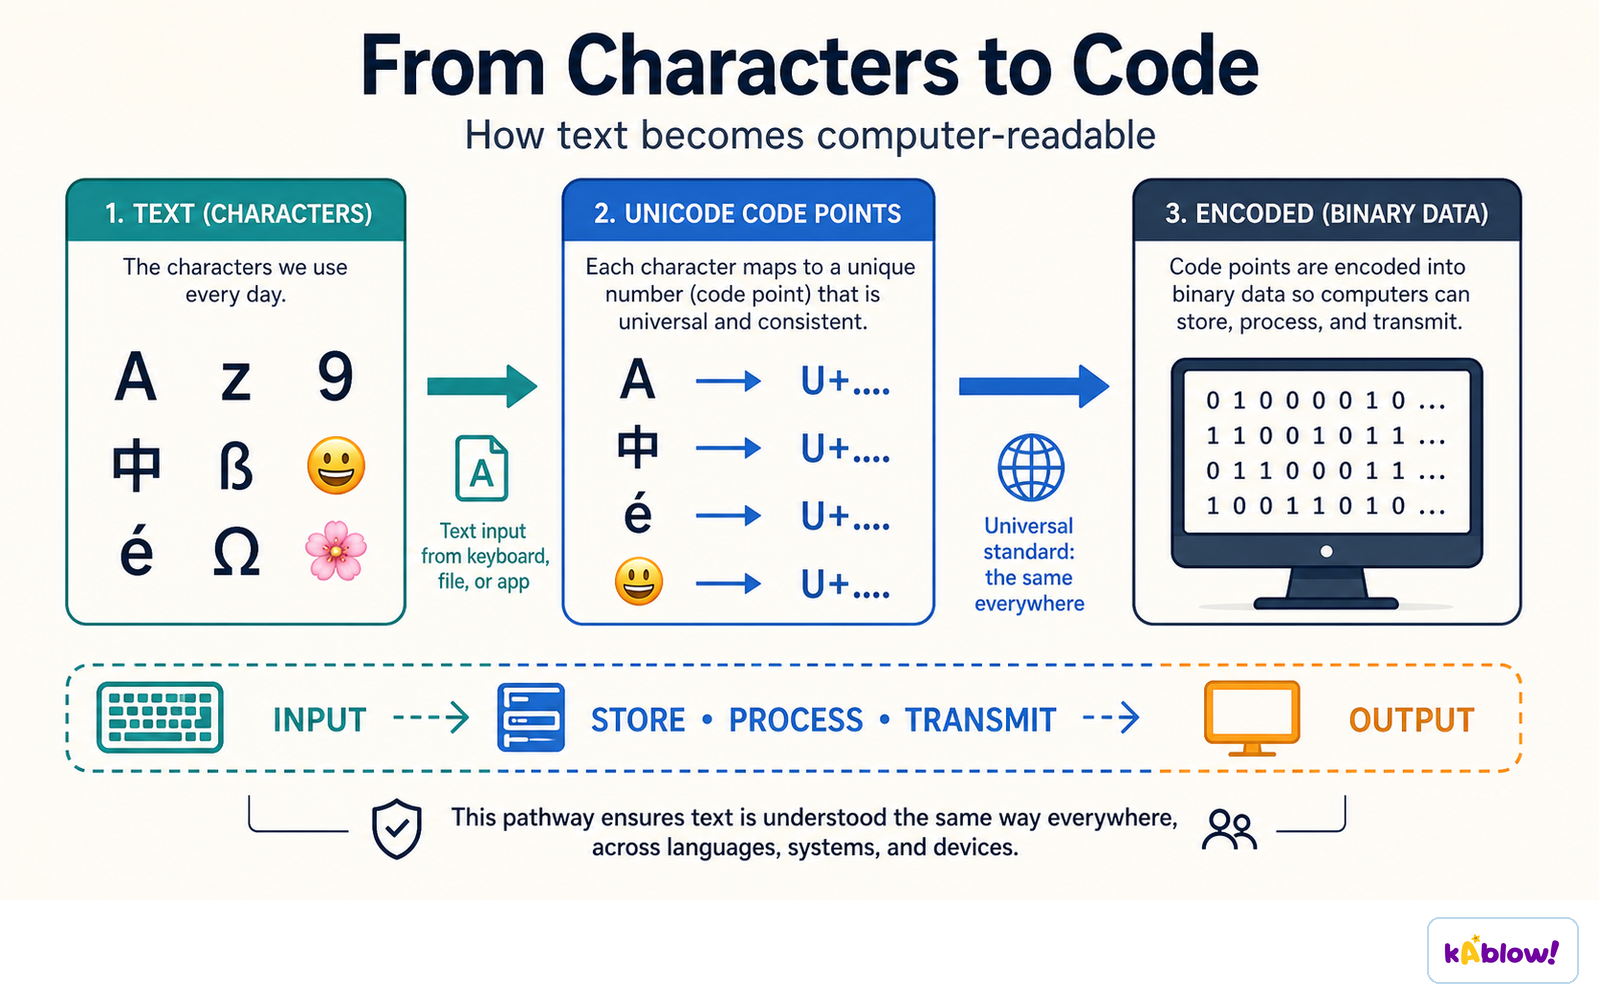
Unicode Encoding Forms: UTF-8 and UTF-16
- UTF-8 is the most popular encoding on the World Wide Web (used by 98.9% of surveyed sites as of January 2026).
- UTF-8 uses variable-length encoding: characters take 1 to 4 bytes; ASCII characters take 1 byte, so it is backward-compatible with ASCII.
- UTF-16 uses 2 or 4 bytes per character and is common in application programs and operating systems.
- Both UTF-8 and UTF-16 can represent all Unicode characters.
How Text Size Relates to Length
- The file size of text depends on the encoding and the characters used.
- In ASCII, each character is 1 byte, so size in bytes equals the number of characters.
- In UTF-8, characters may be 1 to 4 bytes; for example, 'A' is 1 byte, 'é' is 2 bytes, and an emoji is 4 bytes.
- In UTF-16, most characters are 2 bytes, but some (like emoji) are 4 bytes.
- Thus, the same text can have different byte sizes in different encodings.
Why Unicode Matters
- Unicode allows computers to handle multiple languages and scripts in a consistent way.
- It enables global communication and software that works worldwide.
- It supports emoji and other symbols, making digital text more expressive.
- Without Unicode, text would be garbled when moving between systems using different encodings.
Unicode covers the world writing systems and emoji in one standard, where ASCII covers only basic Latin.
슬라이드
연습 문제
무료 미리 보기 — 60개 중 8개 문제. 가입하면 전부 볼 수 있어요.
1.What does ASCII stand for?
Easy- AAmerican Standard Code for Information Interchange
- BAmerican System for Computer and Internet Interchange
- CAutomated Standard Code for Information Interchange
- DAmerican Standard Computer Interface Interchange
2.Which character encoding system is the most popular on the World Wide Web as of January 2026?
Easy- AASCII
- BUTF-8
- CUTF-16
- DEBCDIC
3.ASCII can represent characters from all written languages in the world.
EasyTrue or false?
4.Unicode is an extensible encoding system that has replaced most earlier character encodings.
EasyTrue or false?
5.Why is Unicode preferred over ASCII for representing text in modern applications?
Medium- AUnicode is faster to process than ASCII.
- BUnicode uses fewer bits per character.
- CUnicode can represent characters from many different languages and scripts.
- DUnicode is simpler and easier to implement.
6.Which of the following are examples of character encoding systems? (Select all that apply)
Medium- AMorse code
- BBaudot code
- CPunch card
- DASCII
- EUnicode
7.ASCII was designed to represent all characters in all human languages.
EasyTrue or false?
8.Match each character encoding system to its correct description.
Easy- ASCII
- Unicode
- Baudot code
- An early 5-bit code used in telegraphy
- A 7-bit code for English characters
- An extensible system covering most world scripts
기출 문제
이 주제의 기출 문제 연습이 곧 나와요.
곧 출시